Links

Wednesday, June 22, 2011 Posted by Corey Harrell 0 comments
The links discussed include a triage model, mapping tweets, and an incident analysis write-up.

A Triage Model

Last week I attended my graduation at Norwich University. Not only was it great to finally be done with college but I had the opportunity to sit through presentations including a few on digital forensics. One of the DF presentations was given by Marc Rogers of Purdue University on the Computer Forensics Field Triage Process Model (CFFTPM). Marc’s presentation was informative and afterwards I wanted to learn more about the model so I read a whitepaper on it. For people unfamiliar with the model, the image below shows the different CFFTPM phases.

Source: http://www.mendeley.com/research/computer-forensics-field-triage-process-model/
CFFTPM appears not to be technology dependent which means the model can be used against different platforms in various types of cases. Even knowing this couldn't stop me from thinking about what impact technology may have when trying to implement the model. The majority of the systems I come across run some version of Windows and there has been an increase in the number of Windows 7 systems I’m seeing. If I were to use the model then I take into consideration the volume shadow copies (VSCs) on the newer Windows operating systems. For example, one of the phases in CFFTPM is the examination of the User Profiles by reviewing the following: the home directory, file properties, and registry. If the system contains VSCs then there may be user profile data at different points in time and just triaging the data in the current state might not show an accurate picture of the system. What happens if data is deleted from the user profile prior to the triage? The examiner might not notice this occurred without taking a look at the data in VSCs.

The example holds true for the other triage phases as well. On a few recent cases VSCs contained pertinent data and if I was triaging a system then the VSCs need to be considered. A script and a few tools could parse all of the data - including data in the volume shadow copies – in a short timeframe and still allow me to review all of the information onsite.

Mapping Tweets

A few months ago the article This is What A Tweet Looks Like discussed the metadata stored in a tweet. The metadata contains a wealth of information such as the author's name, account creation date, and the author’s location. I thought about the article when I was reading Creepy, the Geolocation Information Aggregator. Creepy is a python script (still in beta form) that allows people to gather publicly available geolocation information from social networking platforms and image hosting services. The article showed how Creepy can harvest “geolocation information from Twitter in the form of geotagged tweets, foursquare check-in’s, geotagged photos posted on twitter via image hosting services such as yfrog, twitpic, img.ly, plixi and others, and Flickr”.

I didn’t test the python script and my judgment is solely based on the content of the article. Creepy appears to make it extremely easy to map the geolocation information from Twitter and I can see the two sides of how this ability can be used. For investigations it might be helpful to confirm the whereabouts of the person tweeting. On the other side, this ability can make it pretty easy to stalk someone and help identify people’s patterns.

Incident Analysis Write-up

The Carnal0wange blog posted Incident Analysis: Lost Million Dollars in a Minute. The post has a link to their write-up about an incident where a victim’s online banking account was compromised and a sum of money was transferred to Eastern Europe. The analysis involved examining a forensic image of the victim’s machine and a network packet capture. Over the past few years, I’ve seen numerous articles about Trojans being leverage to steal money but until now I haven’t seen any public write-ups about the examination of systems infected with a banker Trojan. The write-up is interesting and I’m thankful the authors shared the information.

One of the conclusions was the “victim's machine is infected via an email by executing a malicious executable file” but the write-up didn’t cover the artifacts to point to this type of delivery mechanism. The next area I’m looking into is the artifacts left by using email as the delivery mechanism so it would have been nice to see how the artifacts looked in an actual incident. Despite this, the write-up still provides a glimpse about the analysis of a system infected with a banker Trojan.

***** Update *****
The Carnal0wange blog had a link to the incident analysis report but has since removed the link and is providing the report by email.
***** Update *****

Mass Malware Still a Threat

Speaking of attack vector artifacts… The ThreatPost article Forget APT, Mass Malware is Still the Big Threat said “type of attacks that most enterprises see today still come from mass malware that defenders haven't yet figured out a good way to stop”. Unfortunately, there are a lot of enterprises who don’t react well to the mass malware problem. The standard SOP is to wipe, reimage, update, and redeploy. The one step missing is the investigation to determine how the malware got onto the system in the first place. Did an exploit target one of the following vulnerable applications: Java, Adobe Flash, Adobe Reader, QuickTime and Internet Explorer? If so which one and how did the exploit get delivered to the system. Did a social engineering trick make an end user infect the system themselves? Did the malware spread through email?

The answer to the how question is crucial for an organization to decide what measures to put in place to better protect themselves for the future. Do resources need to be used to improve a breakdown in the patch management process, offer a security awareness refresher training to employees, implement a new security control, etc.. The attack vector artifacts left on the infected system can help an examiner determine the how of a mass malware infection.

Information Gleamed from Stolen Router

This isn't directly related to DFIR but part of my background includes networking so articles about network security peeks my interest. When I was checking out the InfoSec Resources newsletter I saw the article The Case of the Great Router Robbery which discusses the different information that can be obtained from a stolen router and ways to reduce your exposure if a router is stolen from your organization. I don’t know how many routers are actually being stolen from organizations but it’s good to be informed about the potential risk.
Labels: ,

Why Is It What It Is?

Wednesday, June 8, 2011 Posted by Corey Harrell 1 comments
….. Or more specifically why is Microsoft Office metadata what it is?

Microsoft Office documents contain metadata that may be relevant to a digital forensic examination. The metadata may show when a file was created, modified, printed, or what user accounts were used to perform those actions. Others have already researched the metadata in Microsoft Office 2003 and 2007 documents including providing programs to parse the metadata. A few of the write-ups are: Kristinn Gudjonsson’s Office 2007 metadata post, and Lance Muller’s Office Metadata EnScript & Updated Office 2007 Metadata EnScript posts. I was interested in understanding how different actions taken against a Microsoft Office document affect its metadata.

To help show the relevance of Office documents’ metadata I included the metadata from one of my test Word 2007 documents. Usually I manual examine the information in metadata on an as needed basis but I thought for this post it would be cleaner to show the information in report format. The text below is the output from Kristinn’s read_open_xml_win.pl script ran against a test Word document. The File Metadata section shows when the file was created, modified, printed, and what user accounts were used to perform those actions. Did you notice the last print date/time (2011-05-27T19:09:00Z) occurred one minute before the file was even created (2011-05-27T19:10:00Z)? I’ll touch on this later in the post which is why I pointed it out.

Document name: E:\office metadata testing\word 2007\Xp-2007-1sp.docx
Date:
--------------------------------------------------------------------------
Application Metadata
--------------------------------------------------------------------------
Template = Normal.dotm
TotalTime = 2
Pages = 1
Words = 1
Characters = 9
Application = Microsoft Office Word
DocSecurity = 0
Lines = 1
Paragraphs = 1
ScaleCrop = false
Company = Test-lab
LinksUpToDate = false
CharactersWithSpaces = 9
SharedDoc = false
HyperlinksChanged = false
AppVersion = 12.0000
--------------------------------------------------------------------------
File Metadata
--------------------------------------------------------------------------
title =
subject =
creator = test-2007
keywords =
description =
lastModifiedBy = test-2007
revision = 2
lastPrinted = 2011-05-27T19:09:00Z
created = 2011-05-27T19:10:00Z
modified = 2011-05-27T19:10:00Z

Usernames in Microsoft Office Metadata

Before looking into how different actions against a Microsoft Office document affect its metadata I think it is useful to know more about the usernames reflected in the creator and modifiedby attributes. The usernames are not populated with the name of the user account that performed the action since there is a value in the Windows registry containing the name to use.

When Office 2003 and 2007 is installed there is prompt asking for a user name and company. Those fields are already prepopulated with the information entered when the operating system is installed which is located in the registry key HKLM\Software\Microsoft\Windows NT\CurrentVersion (thanks Greg Kelly for this info). The prompt gives the user an opportunity to either change the user name or company or to leave the fields with the information entered during OS installation.

There is a registry key containing what user name and company was used when Microsoft Office was installed. To locate the registry key the Office program’s GUID must first be determined and this Microsoft article explains how to locate the GUID. The GUID of Microsoft Office programs I tested were 9040110900063D11C8EF10054038389C for Microsoft Office Professional Edition 2003 and 00002109110000000000000000F01FEC for Microsoft Office Professional Plus 2007. The registry key containing the information about the Office installation is: HKEY_LOCAL_MACHINE\SOFTWARE\Microsoft\Windows\CurrentVersion\Installer\UserData\S-1-5-18\Products\{GUID}\InstallProperties. The regowner and regcompany values in the registry key contain the user name and company entered during the Office installation.

The usernames and company information reflected in Microsoft Office documents’ metadata are pulled from the UserInfo registry key of the user account’s NTUSER.DAT hive performing the actions. The names of the two values containing the data in the registry key are UserName and Company. The location of the registry key varies depending on the version of Microsoft Office but the paths below show where the key is located for Office 2007 and 2003.

Microsoft Office 2007: HCU\Software\Microsoft\Office\Common\UserInfo
Microsoft Office 2003: HCU\Software\Microsoft\Office\11.0\Common\UserInfo

Now the question I found myself asking is how are the UserName and Company values initially populated in the UserInfo key? I previously explained the user name and company during Office installation because the entered information is used to populate the UserInfo registry key of the user account that installed Microsoft Office. For the user accounts on the system that are using Microsoft Office but didn’t install it, the values are populated a little different. The first time the user launches an Office application a dialog box appears asking for the user name and initials. The dialog box is prepopulated with the name of the currently logged on user. The information entered in the dialog box is what results in the username value in the user's UserInfo key while the company value comes from the information entered when the Office was installed.

The metadata shown above now has a little more meaning. The username test-2007 is not the name of the user account that created and modified the document but is the name listed in the UserInfo registry key. The name in the UserInfo registry key can be changed at any point but any changes will alter the last write time on the registry key. This means the last write time of the user account’s UserInfo key should be taken into consideration when examining metadata. If the registry key last write time is before the dates/times in the metadata (create, modify, or print) then the metadata reflects what is currently in the user account’s NTUSER.DAT hive. On the other hand, if the registry key last write time is after the metadata timestamps then what is currently in the user account’s NTUSER.DAT hive may not be what was there when the action was taken against the Office document (did I just hear someone whisper check the restore points or volume shadow copies for registry files).

How Actions Change Microsoft Office Metadata

The testing I conducted consisted of creating one document then performing different actions against copies of the document to see how the metadata changed. I only ran the tests against documents created by the following programs: Word 2007, Word 2003, Excel 2007, and Excel 2003. If I test other Office Programs in the future then I’ll update the post to reflect it. The observed changes in the documents’ metadata were consistent across all of the different versions of Office but there were some minor differences between the different file types. The Excel metadata differed from Word in the following ways: there was no revision number, some timestamps contained seconds, and the Save As function didn’t change the documents’ creation date.

I’m providing charts of how the metadata was affected by the different actions taken against the documents. The chart has information in the parenthesis to show what the metadata values were for one set of documents (the timestamps don’t include the date since it was the same for all of the documents).

Here’s the Microsoft Office Word Metadata Changes chart and Microsoft Office Excel Metadata Changes chart.

The charts show how different actions against a Microsoft Office document affect its metadata. There are quite a few takeaways but I’m only going to highlight a few.

* The metadata create date/time reflects when the Office program was opened as opposed to the first time the document was saved
* Copying an Office document doesn’t changed the metadata
* The metadata print date/time only changes when the document is saved after it is printed
* The Save As function results in the Word metadata create and modification date/times being the same while the modification date/time only changes in Excel metadata

Now let’s go back to the metadata I posted above. Do you remember that the last print date (2011-05-27T19:09:00Z) occurred one minute before the file was even created (2011-05-27T19:10:00Z)? There was one action taken against a Microsoft Word document that produced this pattern in the metadata. The action was printing a document then using the Save As function to create a new document. The metadata shown above is from the newly created document.

Hopefully, the sharing of my test results can help others who are pondering the question “why is Microsoft Office metadata what it is”.

How Do You Use Your Skillz

Sunday, June 5, 2011 Posted by Corey Harrell 2 comments
At different times in my personal life I come across everyday people who are experiencing or know of someone having a security issue. Random emails being sent from their email accounts, they clicked on a link that posted something to their friends' Facebook walls, or some rogue program is saying their computers are infected? I expanded jIIr by setting up a Facebook page where I intend to provide security tips to help everyday people protect themselves and be safer, smarter users of the Internet. "Everyday Cyber Security" is meant to be informational and helpful to the "everyday" person so the content is drastically different than my blog. In setting up Everyday Cyber Security I kept reflecting on how I choose to use my DFIR skillz and if I can use my skillz to benefit others. My hope is my personal reflection will encourage you to question how you use your DFIR skillz and if you can be doing more....

I have a certain skillset that the general public does not have. The same is true to the readers of my blog, whether they are seasoned forensicators, students studying the field, or people transitioning into the InfoSec and DFIR fields. I attained my skillset through various means: professional training, self training, researching, and from others who share their experience and knowledge. At times I wonder if I can use my skillset outside of my professional obligations, and if so...how? More importantly I ask myself: can I use my skillz to help others in the DFIR community and the Internet community and the communities in which I live.

I've come across some great people in the DFIR community who are more than willing to share their knowledge and tools; some I have had the pleasure to meet in person while the majority I have not. With that said, there are also people on the other end of the spectrum...those who do not share any information at all. This lack of sharing (whatever the reason) not only inhibits discussions nor offer anything to the larger DFIR community, but at times its very discouraging to the people on the receiving end. Some time ago I asked a question about a DFIR technique. What the question was and where I asked it isn't important. What is important is the response I got to my question, which was along the lines of "with experience you'll know." There was no explanation about a process, no suggested method to carry out the technique, no discussion on how to understand the data, and not even a mention of the possible tools to use. This response left me without any references to help me answer my own question and the other people who witnessed my question didn't have an opportunity for a discussion on the topic. Is this the example I should follow with how to use my skillz?

I attended a service this morning that is relevant to the question of "how do you use your skillz?" The message was about not being dormant and taking the opportunities to help others. How does this apply to DFIR...? It's very easy to say to myself "someone else will step up to share the information, someone else will ask a question sooner or later, someone else will answer the question, or eventually you will know with experience." All of these excuses enable me to be dormant instead of taking the opportunity to share my knowledge and experiences.

The decision I've made with how to use my skillz is to try to give back to the community that has given so much to me. I started the jIIr blog to share my research, experience, and thoughts with the DFIR community since there was a chance others would benefit. Now I'm taking the next step of using my skillz and knowledge to help the Internet community and the community where I live. Everyday Cyber Security is a means to empower people to protect themselves from malicious cyber activities. There are a million different reasons of why I shouldn't use my DFIR skills outside of my professional obligations, but I only need one reason to do it anyway. How about you?
Labels:

Meet the jIIr Symbol

Posted by Corey Harrell 0 comments
About a month ago I was talking with a co-worker when the conversation turned to graphic design. I was thinking about trying to get a few graphics designed for my blog but I had no clue how to go about it. My co-worker knew Julia Hoffman (his sister) who happened to be a graphic design artist and he offered to send her a sketch of my idea. In less than two hours I had two draft pages of my idea and eventually that led to the jIIr symbol. Julia is a great person to work with and her work is impressive. I look forward to working with her on my next graphic project. She is in the process of setting up a website but her college project site is still up if anyone is interested in her work.
Labels:

Triaging My Way

Tuesday, May 17, 2011 Posted by Corey Harrell 7 comments
Your onsite performing a collection or you are in your lab when a computer is given to you and you don’t have a lot of time to answer a few initial questions. How would you quickly determine someone’s activity on the computer? What pictures were viewed, programs ran, files accessed, or removable devices used? Quickly assessing the computer will not only provide information to answer these questions but will also reveal relevant data storage locations for an investigation. This post describes a process – including tools usage – where a few initial questions can be answered in a matter of minutes by examining the user activity on a computer.

Approaching the Triage

I know I promised to write about how to answer questions in less than two minutes by examining user activity on a computer. Before I dive into the land of ones and zeros I wanted to take a step back to talk about the thought process of how to approach the triage. Goals need to be established and a plan needs to be developed on how those goals can be obtained. To accomplish this, the first three questions of the Alexiou Principle can be used:

* What question are you trying to answer?
* What data do you need to answer the question?
* How do you extract that data?

The Alexiou Principle is very versatile since it can be to create analysis design plans, assist with DFIR training (as I described in the Forensicator Readiness post), and guide the thought process for triaging. The first Alexiou Principle question is what question you are trying to answer and this question is pretty self explanatory. As it relates to triage, what are the initial questions to determine if “something” is relevant to the digital forensic examination? The initial questions will vary based on the type of DFIR case and customer needs but the opening paragraph provided a few example questions.

The second Alexiou Principle question is what data do you need to answer the question? The data not only includes data sources such as computers, servers, and people but it also includes what information in those data sources can help answer the questions. Take for example the question was someone accessing the jIIr blog and the only data source available is the person’s computer. What data in the computer can help determine if the person visited my blog? A few areas to check could be the installed software (what web browser are installed), web browser artifacts (history, cookies, or favorites/bookmarks), and maybe the TypedURLs key in the user account’s NTUSER.DAT hive.

The third Alexiou Principle question is how do you extract that data? The tools selected to perform the triage need to be able to extract the data that is required to answer the initial questions. This means the selection of tools should not occur before the data is identified since this may force people to have to work within the confines of the tools. Instead, the selection of tools should be one of the last things completed since the tools to use will be dependent on the goal(s) of the assessment. I wanted to mention this point because I’ve seen numerous times where discussions are started with “should I use this tool” when the discussion should start with this is what I’m trying/need to accomplish.

Triaging User Activity in Under Two Minutes

Now that I’ve explained the thought process of how to approach the assessment of user activity on a computer I’ll walk through an issue I had at one point. I work in corporate environments and as expected the majority of the networks are running Windows domains. A Windows domain can have a significant impact on digital forensic examination because the computer being collected may not contain all of the data relevant to an investigation. The IT department may have assigned home folders to employees using company computers to make it easier for the IT department to back up people’s files. If an organization is using home folders then most likely the organization is encouraging users to store all of their data in their home folders instead of the computers’ My Documents folders. In addition to home folders, the person may be accessing and storing data in network shares. One of the initial questions I need to answer in this type of environment is what data sources - besides the person’s computer – do I need to collect?

Two options to determine what data sources - besides the person’s computer – need to be collected is speaking with the IT department or quickly triaging the computer. IT departments are not known for their great documentation skills so the better option is to triage the computer to find the answer. What data is needed to determine the network shares a person accessed? The data to answer the question could be located in the person’s activity on the computer. Three locations containing user activity are the registry, system restore points/volume shadow copies’ registry files, and the link files in the user account’s profile. For additional references on the evidentiary value of the registry check out the book Windows Registry Forensics while the Digitial Forensic Search custom Google query for link files can be used to learn more about them.

How do you extract data stored in registry and link files? I took into account the following for my tool selection: had to extract the data, had to be fast, had to be command line tools (you’ll see why), and my preference was for tools already in my toolbox. Harlan Carvey’s Regripper was chosen to parse the registry files, Harlan’s RipXP (included in the Regripper downloaded) was chosen to parse the registry files in system restore points, a modified version of Harlan’s lslnk.pl script to parse the link files and FTK Imager to mount the hard drive/image.

The example I’m using is to determine the network shares accessed but keep in mind this will work for other types of user activity since the registry and link files store the information. I promised to write about how to answer a few initial questions in less than two minutes by assessing the user activity on the computer. Here goes ………..

Mount the Image/Hard Drive

The situation will dictate if the computer’s hard drive will be examined using a write blocker or if the forensic image of the computer’s hard drive will be examined. The triage will work the same regardless if the hard drive or image is being examined. When quickly triaging a system my preference is to parse the data of interest where it’s located instead of copying the data to my forensic computer. The image/hard drive has to be mounted to the forensic computer in order for the registry and link files to be parsed in their storage locations and this can be accomplished using FTK Imager version 3.0 with the “File System / Read Only” mount option (allows access to system restore points). F:\[root]\ is the path to the root of the volume I’m examining and the commands below will reflect the path.

User Activity Stored in Registry

A user account’s NTUSER.DAT registry hive stores configuration information and the user account activity on the system. A quick way to identify registry keys of interest (in addition to the Windows Registry Forensics book) is to reference registry checklists like AccessData’s Registry Quick Find Chart or review the Regripper’s plugin files. The three registry keys of interest are: Map Network Drive MRU since it lists the recently mapped network drives, MountPoints2 since it lists devices accessed, and RunMRU since one way to access network shares is using the run dialog box. Regripper has plugins to parse all three registry keys and the commands for running the command-line version of Regripper with the output being redirected to a text file is below.

rip.exe -r "F:\[root]\Documents and Settings\Administrator\NTUSER.DAT" -p mndmru >> rip-drives.txt

rip.exe -r "F:\[root]\Documents and Settings\Administrator\NTUSER.DAT" -p mp2 >> rip-drives.txt

rip.exe -r "F:\[root]\Documents and Settings\Administrator\NTUSER.DAT" -p runmru >> rip-drives.txt

The first command uses -p mndmru to specify the plugin for the Map Network Drive MRU registry key. The output of this command identifies four network shares that were mapped to the user account of interest as shown below.

Map Network Drive MRU
Software\Microsoft\Windows\CurrentVersion\Explorer\Map Network Drive MRU
LastWrite Time Sat May 14 18:13:18 2011 (UTC)
MRUList = dcba
c \\192.168.1.80\Map Drive 2
a \\192.168.1.80\Map Drive D
b \\192.168.1.80\Map Drive 1
d \\192.168.1.80\Map Drive 3

The second command uses -p mp2 to specify the plugin for the MountPoints2 registry key. The output of this command also identifies the same four network shares. A portion of the output is shown below.

MountPoints2
Software\Microsoft\Windows\CurrentVersion\Explorer\MountPoints2
LastWrite Time Sat May 14 18:19:16 2011 (UTC)

Remote Drives:
Sat May 14 18:13:18 2011 (UTC)
##192.168.1.80#Map Drive 3
Sat May 14 18:04:37 2011 (UTC)
##192.168.1.80#Map Drive 2
Sat May 14 17:59:27 2011 (UTC)
##192.168.1.80#Map Drive 1
Sat May 14 17:56:10 2011 (UTC)
##192.168.1.80#Map Drive D

The third and last command uses -p runmru to specify the plugin for the RunMRU registry key. The output of this command shows the same device with the four network shares (192.168.1.80) as well as a new device (192.168.2.50). The output doesn’t show any network shares being accessed but it does attempts were made to access the devices in a method that will display the network shares (\\IP-Address). The runmru output is shown below.

RunMru
Software\Microsoft\Windows\CurrentVersion\Explorer\RunMRU
LastWrite Time Sat May 14 18:22:00 2011 (UTC)
MRUList = bca
a cmd\1
b \\192.168.2.50\1
c \\192.168.1.80\1

User Activity Stored in System Restore Points (or Volume Shadow Copies) Registry Files

Windows system restore uses restore points to return system files and settings to an earlier point in time for computers running Windows 2000 or XP. Windows Vista and 7 uses volume shadow copies instead of restore points. Registry files covering different points of time in the past are located the restore points and volume shadow copies, and these files may contain additional information about user account activity. To parse the registry hives in the volume shadow copies a simple batch file using the command-line version of Regripper can be used. RipXP.exe can be used to parse a key in the current registry hive and the registry hives in the restore points (RipXP.exe parses the current registry hive so the rip.exe commands can be skipped when using RipXP.exe in this triage method). RipXP.exe requires three switches: -r specifies the current registry hive, -d specifies the restore point directory, and –p specifies the plug to use. The commands to parse the three registry keys of interest with the output being redirected to a text file are below.

ripxp.exe -r "F:\[root]\Documents and Settings\Administrator\NTUSER.DAT" -d "F:\[root]\System Volume Information\_restore{3F806DB1-464B-46B0-B724-4376EC868222}" -p mndmru >> rip-rp-mndmru.txt

ripxp.exe -r "F:\[root]\Documents and Settings\Administrator\NTUSER.DAT" -d "F:\[root]\System Volume Information\_restore{3F806DB1-464B-46B0-B724-4376EC868222}" -p runmru >> rip-rp-runmru.txt

ripxp.exe -r "F:\[root]\Documents and Settings\Administrator\NTUSER.DAT" -d "F:\[root]\System Volume Information\_restore{3F806DB1-464B-46B0-B724-4376EC868222}" -p mp2 >> rip-rp-mp2.txt

The output of all three commands will be similar to the Regripper output I showed before with the exception the registry keys in all of the restore points being displayed. I'm only showing a portion of the Map Drive MRU registry key output since it demonstrates how the output will look. As can be seen below, RipXP.exe output first displays the registry data from the current registry hive before the restore point registry data. The current Map Drive MRU key has four mapped network drives while the restore point shown only has three.

RipXP v.20090818
Launched Sat May 14 19:46:12 2011 Z

F:\[root]\Documents and Settings\Administrator\NTUSER.DAT
Map Network Drive MRU
Software\Microsoft\Windows\CurrentVersion\Explorer\Map Network Drive MRU
LastWrite Time Sat May 14 18:13:18 2011 (UTC)
MRUList = dcba
c \\192.168.1.80\Map Drive 2
a \\192.168.1.80\Map Drive D
b \\192.168.1.80\Map Drive 1
d \\192.168.1.80\Map Drive 3
----------------------------------------
Restore Point Info
Description : access share files
Type : System CheckPoint
Creation Time : Sat May 14 18:08:38 2011

F:\[root]\System Volume Information\_restore{3F806DB1-464B-46B0-B724-4376EC868222}\RP10\snapshot\_REGISTRY_USER_NTUSER_S-1-5-21-1214440339-1708537768-725345543-500

Map Network Drive MRU
Software\Microsoft\Windows\CurrentVersion\Explorer\Map Network Drive MRU
LastWrite Time Sat May 14 18:04:37 2011 (UTC)
MRUList = cba
c \\192.168.1.80\Map Drive 2
a \\192.168.1.80\Map Drive D
b \\192.168.1.80\Map Drive 1

User Activity Stored in Link Files

The registry provides a wealth of information but link files is another location containing information about a user account activity on a computer. A link file is created when a person accesses a file on their computer's hard drive, removable media, or a network share. The link file contains information about the file including its storage location which will show someone accessing network shares. A few locations containing link files are:

Windows XP: C:\Documents and Settings\username\Recent and C:\Documents and Settings\\Application Data\Microsoft\Office\Recent

Windows Vista and 7: C:\Users\username\AppData\Roaming\Microsoft\Windows\Recent and C:\Users\\AppData\Roaming\Microsoft\Office\Recent

One of my requirements for a tool to parse link files was it had to be a command line tool. My reasoning is command-line tools can be used in scripts but more importantly command-line tools can be used in batch files to parse artifacts in volume shadow copies. I couldn't find a tool to meet my needs. Harlan provided the lslnk.pl script in WFA 2nd edition and it displays the information contained in link files. However, lslnk.pl only works against individual files when I needed a tool to parse an entire directory of link files. I'm not a programmer and I don't know Perl but I can use search engines so I decided to try to modified lslnk.pl. The first modification I made was to enable lsnk.pl to parse all of the link files in a directory with the output being in report format. The modified script - lslnk-directory-parse.pl - worked fine but the output wasn't the best for filtering data. I needed the output to display all of the information from a link file on one line so I perform a search I can see all information for a specific link file. I made another change to make the output contain one link file per line in comma delimited format and this resulted in the lslnk-directory-parse2.pl script. Both modified scripts can be found in the Yahoo Win4n6 group's tools folder. The only parameter required by the script is the directory to parse as shown below.

C:\Perl>lslnk-directory-parse2.pl "F:\[root]\Documents and Settings\Administrator\Recent" > lsnk-parse2-output.txt

The output is a comma delimited text file and this means it can be opened in Excel/Calc (to see how to import a text file in Excel check out my posts Reviewing Timelines with Excel or Reviewing Timelines in Calc). Opening the text file at this point will show the information from all of the link files instead of the information specific to the question at hand which is what network shares did an account access. The text file can be searched prior to it being reviewed in Excel/Calc and I use Grep (available in UnxUtils) to do this. There are numerous characteristics to search on such as filenames, directory paths, file extensions, removable media, and network shares. That's right, link files indicate if person accessed a file on a network share. The lslnk-directory-parse2.pl can be redirected to Grep for searching prior to the creation of the text file. The command below shows the lslnk-directory-parse2.pl output being searched for the word "network share" (the binary-file=text switch forces Grep to see the output as text).

C:\Perl>lslnk-directory-parse2.pl "F:\[root]\Documents and Settings\Administrator\Recent" | grep.exe -i --binary-files=text "network share" > lsnk-parse2-output.txt

The output file is still a comma delimited file but the only link files present will be the ones with the phrase "network share" in its information. Reviewing a portion of the output not only shows files accessed on the network shares identified previously with Regripper and RipXP but it also identifies files accessed in a new share (\\192.168.2.50\Share) as shown below.

Summary

The triage extracted data from registry and link files to answer the question of what network shares a person accessed. There was some redundancy in the extracted data since both locations showed the same user account activity (same network share access). However, at times one location may reveal information that is not present in the other. I promised to write about how to answer a few initial questions in less than two minutes by examining the activity on the computer. It took me less than one minute to run Regripper, RipXP, and lslnk-directory-parse2.pl, and to examine the output from the three tools. Within this one minute I was able to determine the network shares a user account had readily available access to (mapped drives) and network shares accessed. The process can be even quicker by creating a batch file with all of the commands since a batch file can just be executed. I answered a question network share access but the process I described should not be limited to only this activity. Different registry keys in combination with information contained in link files can be used to quickly determine someone’s activity on a computer.

Coming To A System Near You

Wednesday, May 11, 2011 Posted by Corey Harrell 0 comments
According to Websense, there is a new trend where cyber criminals are spreading malware by taken advantage of Google Image search rankings. The attack involves poisoned pictures being displayed in Google’s image search results which when clicked redirects a user to a malicious site. As I was in the middle of putting together this write-up the Unmask Parasites blog had a great post, Thousands of Hacked Sites Seriously Poison Google Image Search Results, on how the websites involved in this attack were compromised and how the Google image search is poisoned while Brian Krebs wrote his own article on the subject Scammers Swap Google Images for Malware.

Those write-ups provided good information about the Google image search poisoning technique but I was approaching the topic from a different angle. My approach is from the perspective of the digital forensic practitioner who investigates this attack on a computer (client side). The Google image search is being leverage to spread malware but one important question I haven’t seen addressed is what are the potential artifacts that indicate the malware came from a Google image search. Along the same line of thinking, how are the artifacts of this delivery mechanism different than a Google web search, SPAM email, or a network share? The answer to these questions will be discussed in detail, hopefully before the Google image search attack comes to a system near you.

Simulation Setup

I tried to simulate how a user would perform Google searches for a selected topic. The topic I selected for my searches was the news of the day on 05/02/11 since the media coverage was everywhere. The topic seemed like a candidate for cyber criminals to try to leverage for spreading malware. I performed Google web and image searches using different word combinations until I had my first sign of an infection which was a warning message saying my unpatched Windows XP SP3 system was infected. I pretended to be a “normal” user to get rid of the warning by clicking cancel but in a short period of time the computer was held hostage by a fake antivirus program.

The Search Hit Culprit

I usually write my posts the way I conducted the examination. The malware is located then I work backwards in time examining the system activity to identify the initial infection vector. I’m taking a slightly different approach for this write-up by first explaining what the user saw followed by what the digital forensic practitioner would see during an examination. The potential artifacts of the Google image search being used to deliver a payload is shown through the DF perspective.

***** Heads Up: some of the URLs and domains mentioned in this write-up were malicious at one point in time so caution should be used if anyone tries to access them for their own research. All URLs were sanitized (or purposely only shown in images) to prevent anyone from accidently accessing the URLs. *****

User Perspective 1

Starting at 09:41:38 PM on 05/02/11 Google web and image searches were performed looking for sites and images about the news of the day. After about 20 minutes I performed the Google image search shown in the picture below. The highlighted image in the first row of search results is the image I access which lead to my system being infected.

DF Perspective 1

The above picture shows what a user sees when performing a Google image search. Different tools/techniques can be used to see what the search looks like on a system post mortem. The picture below shows the part of the timeline where the Google image search occurred and the images in the timeline were downloaded because of the search.

User Perspective 2

Clicking on the image highlighted in red resulted in the Internet Explorer window disappearing and being replaced by the warning message below.

It wasn’t too long until an Internet Explorer window appeared which was pointing to the malicious mlrglrqj.co.cc domain as illustrated below.

DF Perspective 2

At this point a Google image search resulted in the Internet Explorer browser being redirected to the mlrglrqj.co.cc domain where a fake online scanner was located. To see how this occurred forensically, the activity of the Google image being accessed needs to be examined. The portion of the timeline below shows the Google image URL that was accessed and this resulted in the image (line 151879) and a webpage (line 151880) being downloaded to the system. The timeline also shows a webpage, mlrglrqj.co[2].htm, being downloaded six seconds after the image was accessed (line 151881).

The URL in the above picture shows that when the Google image was accessed it brought the user to hxxp://pimpit.com/pr-Osama-Binladen-Dead.html (the imgrefurl variable contained the URL) and the webpage was using an image located at hxxp://theblackboxoffice.com/wp-content/uploads/2010/08/binladen_dead_alive.jpg (the imgurl variable contained the URL). Besides the image of interest, the only other file downloaded to the system before the browser redirect was an htm file named CA16L2DT.htm (this file was uploaded to jsunpack and can be viewed here). I examined CA16L2DT.htm to see if I could find in the file what caused the browser redirect. There was a reference to the t3.gstatic.com domain so I decided to look into the domain a little closer. The first Google search hit for the domain was a thread in a CNET forum titled “Phishing on Google Image Search - t3.gstatic.com/images” from July 2010. A person in the thread mentioned how Kaspersky antivirus was blocking the t3.gstatic.com domain due to it being a phishing attack. I did a search for the domain using the Malware Analysis Search which found malware samples associated with URLs that looked similar to the URL I found in the CA16L2DT.htm file (two of the malware sample reports can be found here and here). I wasn’t able to confirm what caused the browser redirect but I was able to determine the pimpit.com domain was involved with the redirect and a suspicious URL was present on pimpit.com’s webpage.

User Perspective 3

A “Windows Security Alert” appeared on the fake online scanner as shown below.

Shortly after the “Windows Security Alert” a program named XP Home Security appeared on the system. XP Home Security was the program holding the test system hostage.

DF Perspective 3

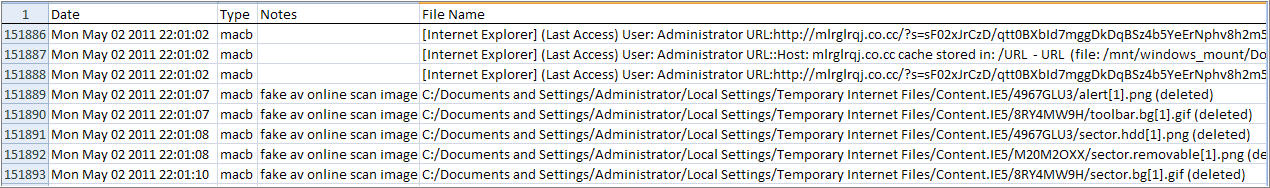
User Perspective 3 showed the payload of the attack wasn’t the fake online scanner but was the XP Home Security program which was successfully installed on the system. Continuing with the examination of the timeline, the activity on the system indicates the fake online scanner was still open as can be seen in the timeline below.

After the fake online scanner activity there was an Internet Explorer history entry for the following URL hxxp://mlrglrqj.co.cc/file/sc1/SecurityScanner.exe. Immediately after this URL was accessed there were a few registry modifications and the creation of a prefetch file indicating the SecurityScanner.exe program was executed. The picture below shows this activity in the timeline.

The timeline showed there were no indications of a software exploit (vulnerable programs executing, new files appearing on system ,etc..) on the system so it doesn’t appear an exploit was responsible for installing the malware. However, the administrator user account was responsible for the suspicious Internet activity so the account's recent activity was examined to shed light on how the malware was installed. I used Regripper to examine the user activity stored in the registry by parsing the administrator user account’s NTUSER.DAT registry hive. The MUICache registry key entry in the Regripper report shows the administrator user account executed the Security Scanner.exe and ieh.exe programs. The MUICache data for these programs are shown below:

Software\Microsoft\Windows\ShellNoRoam\MUICache
LastWrite Time Tue May 3 02:09:07 2011 (UTC)
     C:\Documents and Settings\Administrator\Local Settings\Temporary Internet Files\Content.IE5\4967GLU3\SecurityScanner[1].exe (SecurityScanner[1])
     C:\Documents and Settings\Administrator\Local Settings\Application Data\ieh.exe (ieh)

The lack of exploit artifacts and the MUICache registry key data indicate the administrator user account installed the malware which was exactly what happened. Further examination of the system identified the ieh.exe file as the program holding the system hostage and a VirusTotal scan of the file had a detection rate around 30%.

Potential Google Image Search Delivery Artifacts

At this point the user and digital forensics perspectives showed malware being installed on a system because of a Google image. The purpose of this post was to identify the potential artifacts of a Google image search being used to deliver malware which is why I stopped writing about the DF perspective once the malware was installed on the system. The portions of the timeline in my write-up showed had a lot of deleted files which helped explain how this attacked happened. Most likely deleted files will be over written since the system won’t be preserved within 30 seconds of being infected. However, the potential artifacts of the Google image search being used as the delivery mechanism may still be present on a system in the Internet browsing history. If the browser history artifacts occur around the time when malware firsts executes on a system (prefetch files, registry modifications, etc) then this may indicate the Google image search was used as the delivery method. For example, the malware executed on my test system around 10:03 PM on 05/02/11 and the Internet browsing history around this time showed a Google image being accessed followed by my Internet browser visiting a malicious domain. My browser history showing the Google image search is below.

All Things Encase

Thursday, May 5, 2011 Posted by Corey Harrell 0 comments
I use a range of tools to perform digital forensics and these tools fall into different categories such as free, open source, and commercial tools. Some readers of this blog may have picked up on that Encase is one of the commercial tools in my toolbox. I thought I would share some of the interesting links I came across over the past month about Encase.

Forensic Analysis Techniques Using Encase

Lance Muller put together a couple of posts about computer forensics analysis techniques using Encase. First up is the post Basic Computer Forensic Analysis Techniques in Encase which outlines the techniques commonly used in cases and techniques specific to certain types of cases. His second post is General Forensics (using EnCase Enterprise) Flow chart and this provides some ideas on the different ways to use Encase Enterprise in support of investigations, incident response, and e-discovery.

Lance mentioned that both posts are not meant to be all inclusive lists but are to be used as starting points. He also said in one of the posts that the type of investigation will impact the techniques to use. I couldn’t agree more with his comment. To help determine what techniques to use a person should take a step back before an image is loaded into Encase or a servlet is pushed across the network. Taking a step back provides time to think about the goals of their forensic examination, the questions that need to be answered, and what data is needed to answer those questions. This quick reflection (or better yet an analysis design plan) will not only help determine what techniques/activities are needed to extract the data of interest but can also help keep the examination focused on what the customer wants or needs.

A New Option for Creating Timelines

Kristinn Gudjonsson released version 0.52 of log2timeline in April. I was checking out the change log to see what was new and one of the changes is the ENCASE_DIRLISTING input module. According to the change log, this new module imports a text file exported by Encase which contains the file listing of an image. It’s good to see more options for creating timelines. Now we have the Sleuthkit, Sleuthkit with Harlan’s timeline tools, Sleuthkit with log2timeline, FTK file listing, FTK file listing with log2timeline, Encase enscript, Encase file listing, and now the Encase file listing with log2timeline. Having options lets me test the different ways to create timelines and choose the method that best meets my needs. An additional thought that came to me as I was typing the various options was to do a write up on the different ways to create timelines. One more idea added to my blog hopper.

Encase version 7

Just in case for anyone who missed the announcements from the Guidance Software’s advertising machine, Encase version 7 is on the horizon. If you’re interested in some of the new features or changes check out Lee Whitfield’s podcast Episode 36 Encase Forensic 7 and Geoff Black’s Forensic Gremlins post Encase 7 Sneak Peek (NYC).

Besides the  layout of the user interface, two new improvements I’m also interested in are the index and email functionality. At times and in certain types of cases, I need the flexibility to search an index on the fly so I’m curious how well the new index will work. I always found the email analysis in Encase to be lacking so I'll welcome any improvements in this area. Unfortunately, the new email still lacks support for Lotus Notes version 8.X but I have other options to address this need.

Encase Version 7 Preview

Speaking of wanting to see the new features in Encase 7, Guidance released the Encase 7 preview software last weekend. Paul Bobby of SecureArtisan has been testing the software and sharing his thoughts on his blog. Encase v7 Preview, Encase v7 Conditions, and Tagging in Encase v7 are his posts so far. Hopefully I’ll find some time over the next week to play with my preview software. I was a little disappointed to see that the software is restricted to the evidence files provided by Guidance. I was looking forward to throwing my images and email files at the new version to see how it performs … at least in the meantime I can see the new layout.
Labels: ,